ollama
Pauses background model upgrades to improve embedding and request execution performance.
Prioritizes active request latency over asynchronous background maintenance tasks.
- Licence
- MIT
- Platform
- Linux, macOS, Windows
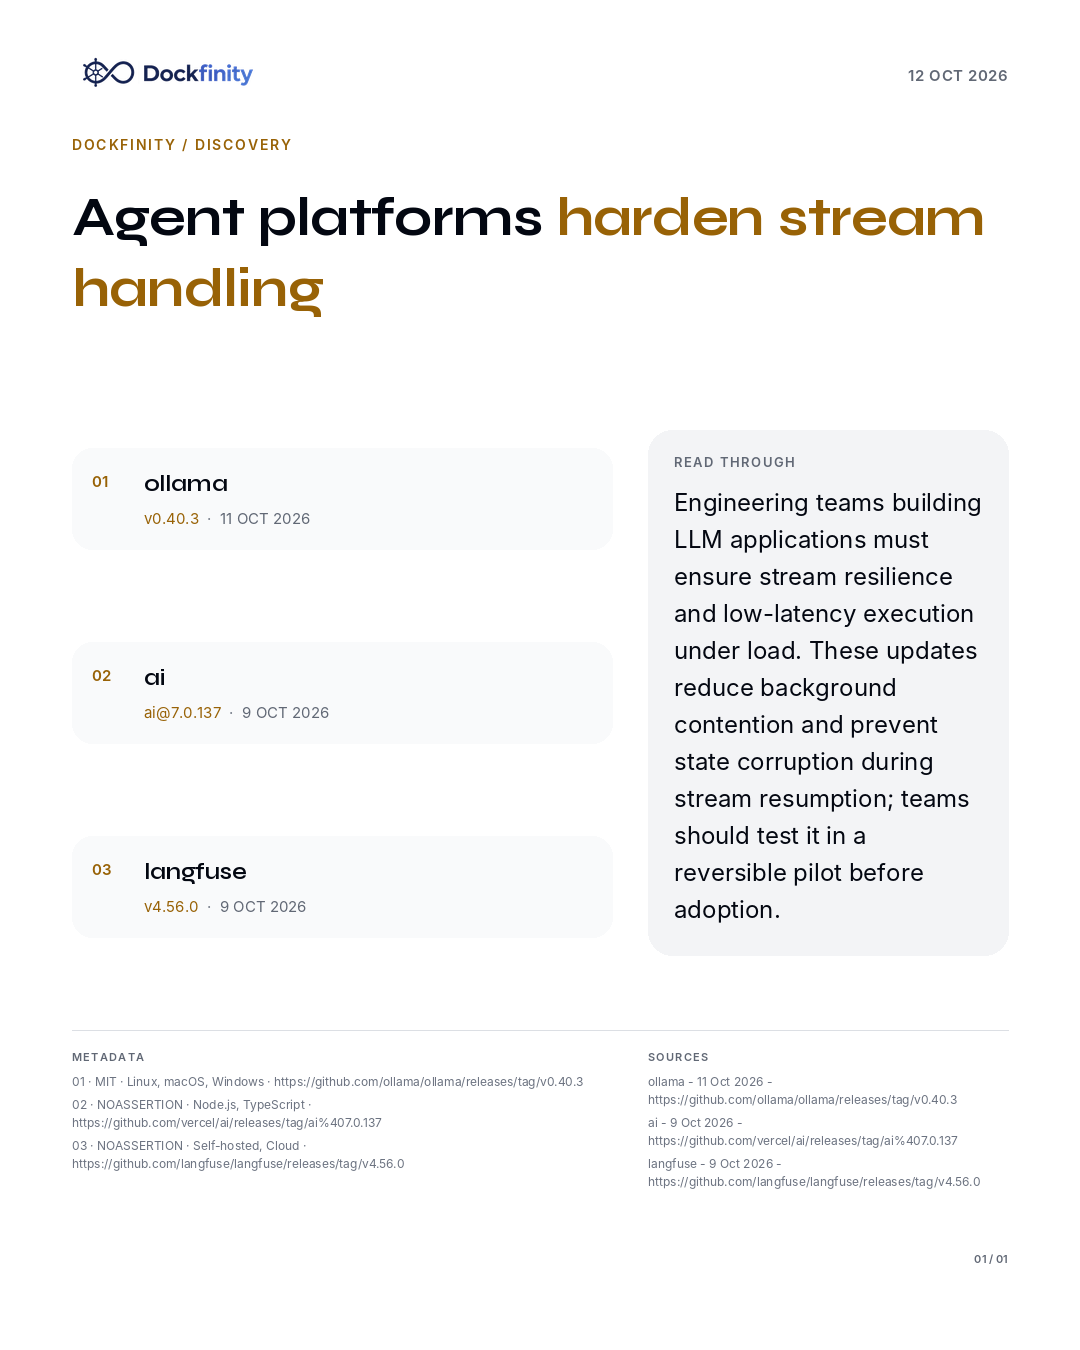
Agent platforms harden stream handling
Pauses background model upgrades to improve embedding and request execution performance.
Prioritizes active request latency over asynchronous background maintenance tasks.
Discards unrelated message state when reading resumed AI streams.
Prevents state leakage across interrupted and resumed LLM stream connections.
Revamps evaluation model results and adds read-replica routing for analytics queries.
Offloads heavy scoring analytics from primary operational databases to read replicas.
Engineering teams building LLM applications must ensure stream resilience and low-latency execution under load. These updates reduce background contention and prevent state corruption during stream resumption; teams should test it in a reversible pilot before adoption.

The same card posted on social. Open it for the full size.